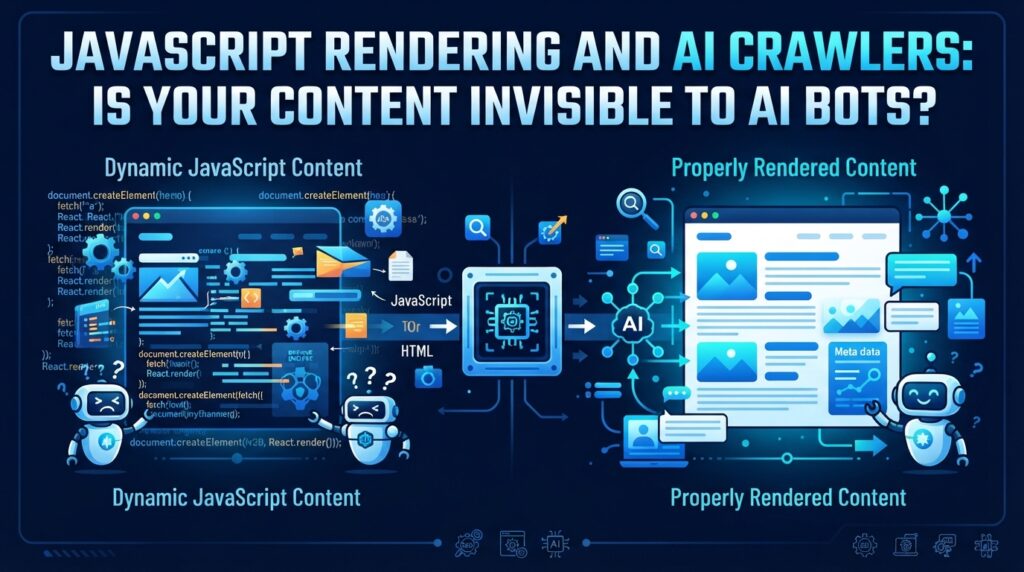
JavaScript makes websites more interactive, faster to use, and easier to navigate. It helps create modern designs, animations, menus, and dynamic content. However, it can also create problems when search engines and AI crawlers try to read your website.
A page may look perfect in Chrome but show very little content when a crawler visits it. This happens when important text loads only after JavaScript runs. Some crawlers can process JavaScript, while others may only read the HTML returned by the server.
This creates an important question for website owners: can AI platforms actually see and understand your website content?
Understanding JavaScript SEO AI Crawlers is becoming an important part of technical SEO and Generative Engine Optimization (GEO). If your content is hidden behind scripts, delayed API calls, or client-side rendering, some crawlers may not receive the information they need.
The good news is that you do not always need to rebuild your website. Simple tests can help you identify rendering problems, and solutions such as server-side rendering and prerendering can make important content easier to access.
In this guide, we will explain how JavaScript rendering works, which AI crawlers have documented capabilities, how to test your pages, and what you can do to improve content visibility.
What Is JavaScript Rendering?
JavaScript rendering is the process of turning JavaScript code into the content and layout visitors see in their browsers.
For example, imagine a website page that contains an article title, an introduction, and several sections. The server may initially send only a basic HTML document. JavaScript then requests the article data and adds the title and paragraphs to the page.
A human visitor usually sees the complete article after the browser finishes loading everything. However, a crawler that does not execute JavaScript may receive only the original HTML.
This difference is important for SEO and GEO.
Client-Side Rendering (CSR)
Client-side rendering happens when the browser uses JavaScript to build most or all of the page content.
The server may return a basic HTML file with a script reference and an empty content container. The browser downloads the JavaScript, runs it, requests information, and displays the finished page.
For example:
<div id="root"></div>
<script src="/app.js"></script>
The actual article may appear only after app.js runs.
This approach is common in modern applications built with React, Vue, and Angular. It can provide smooth user experiences, but it creates additional work for crawlers.
client-side rendering AI is a concern because not every AI crawler has publicly documented JavaScript execution capabilities. If a crawler reads only the initial HTML, it may miss content added later.
Server-Side Rendering (SSR)
Server-side rendering creates the page HTML on the server before sending it to the browser.
Instead of receiving an empty content container, the visitor and crawler receive HTML that already contains the main article text.
For example:
<h1>How JavaScript Rendering Works</h1>
<p>
  JavaScript rendering helps browsers display
  dynamic website content.
</p>
The browser can still use JavaScript to add interactive features, but the important content is already available.
This is useful for SEO because crawlers can access the main information without depending entirely on client-side scripts.
Static Rendering and Prerendering
Static rendering creates HTML pages ahead of time rather than building them for every request.
Prerendering follows a similar idea. A tool or build process prepares an HTML version of a page so that its content is available immediately.
These approaches can help websites with many informational pages, landing pages, product descriptions, and blog articles.
Google recommends server-side rendering or pre-rendering as useful solutions because they make content faster and easier for crawlers to access.
How AI Crawlers Process JavaScript
Not every crawler works like a modern web browser. Some crawlers can execute JavaScript, while others fetch website HTML without publicly documented rendering support.
This is why AI bots JavaScript compatibility deserves attention when building a GEO strategy.
Which AI crawlers can execute JavaScript?
The following table separates documented behavior from capabilities that have not been publicly confirmed.
| Crawler | JavaScript rendering status | Important detail |
|---|---|---|
| Googlebot |
Supported
|
Uses an evergreen Chromium-based renderer |
| OpenAI OAI-SearchBot |
Not documented
|
OpenAI does not specify JavaScript rendering in its crawler documentation |
| OpenAI GPTBot |
Not documented
|
Its published purpose is model-training data collection |
| Anthropic Claude-SearchBot |
Not documented
|
Anthropic documents its search purpose, not rendering capabilities |
| Anthropic ClaudeBot |
Not documented
|
Its published purpose includes model-development data collection |
| PerplexityBot |
Not documented
|
Perplexity identifies its crawler but does not specify JavaScript rendering |
Sources: Google’s JavaScript SEO documentation, OpenAI’s crawler documentation, and Anthropic’s crawler documentation.
There is an important difference between undocumented and unsupported. We should not claim that a crawler definitely cannot execute JavaScript when its provider has not confirmed its capabilities.
Google, however, clearly documents that Googlebot uses Chromium to render JavaScript. Google also warns that not all bots can run JavaScript.
For website owners, the safest approach is to make important content available in the original HTML instead of depending on a crawler’s ability to execute scripts.
How to Check If AI Crawlers Can See Your Content
You do not need expensive SEO software to identify basic JavaScript rendering problems. Two simple tests can help you understand what your server sends before a browser executes JavaScript.
1. Use the View Source Test
The first test is simple and takes less than a minute.
Follow these steps:
-
Open an important page on your website in Chrome.
-
Right-click anywhere on the page.
-
Select View Page Source.
-
Press Ctrl + F to search for your main heading.
-
Search for a few important paragraphs from the article.
-
Check whether the content appears in the original HTML.
If your article text is visible in the source, that is a good sign.
If you only find an empty container, such as a div with an ID, your content may depend on JavaScript to appear.
This is the view source test.
However, remember that View Source shows the original server response, not the final page after JavaScript runs. A missing paragraph does not automatically mean Google cannot index it. Google may render the page later.
2. Test Your Page With Curl
Curl is a command-line tool that requests a webpage and displays the response received from the server.
It can help you check whether important content exists in the original HTML.
Open your terminal or command prompt and enter:
curl -L https://example.com/your-page/Replace the example URL with your actual webpage.
To search the returned HTML for a specific heading, you can use:
curl -sL https://example.com/your-page/ | grep -i "your main heading"You can also test a response using a named crawler user agent:
curl -sL -A "OAI-SearchBot" https://example.com/your-page/This helps identify whether your server returns different HTML based on the user agent.
Important: Changing the user agent does not turn curl into a real AI crawler. It only changes the user-agent header. It does not execute JavaScript or reproduce every crawler’s network behavior.
3. Compare the Original HTML With the Rendered Page
You should compare two versions of the same webpage:
-
Original HTML: The content received directly from the server.
-
Rendered HTML: The content available after the browser executes JavaScript.
Example of a rendering problem
ORIGINAL HTML
<div id="article"></div>
<script src="/app.js"></script>
RENDERED HTML
<h1>Complete SEO Guide</h1>
<p>Learn how to improve website visibility...</p>A browser can display the finished article, but a crawler that only reads the original HTML may not receive its content.
For Google, you can use the URL Inspection tool in Google Search Console or the Rich Results Test to examine the rendered page, loaded resources, and JavaScript errors.
What Is Hydration and Why Can It Hide Content?
Hydration is a process that connects JavaScript functionality to HTML that has already been generated.
For example, a website may send a complete article through server-side rendering. JavaScript then loads and makes buttons, menus, filters, and other interactive elements work.
Hydration is normally helpful, but problems can occur when it is implemented incorrectly.
Common Hydration Problems
Here are some issues that can affect website content:
-
The server sends incomplete HTML.
-
JavaScript removes existing content during hydration.
-
An API request fails before the article loads.
-
Content appears only after a user clicks a button.
-
Important sections are delayed until scrolling.
-
A JavaScript error prevents the page from finishing its rendering process.
These issues can lead to hydration content hidden problems.
For example, imagine a website that displays product descriptions only after a visitor clicks an accordion button. Some crawlers may not interact with that button, so they may never receive the information.
The better solution is to keep important text available in the initial HTML and use JavaScript for additional interactions.
How to Fix JavaScript Rendering Problems
If your website depends heavily on JavaScript, you do not necessarily need to remove it. You need to make sure that important information is accessible without relying entirely on client-side execution.
1. Implement Server-Side Rendering
Server-side rendering is one of the most useful solutions for JavaScript-heavy websites.
With SSR, your server creates the HTML before sending it to the visitor. This means your main heading, paragraphs, links, and other important content are already present in the response.
Frameworks such as Next.js and Nuxt support server-rendering approaches.
For example, a React website can generate article HTML on the server while still using React components for interactive features.
This approach supports server-side rendering GEO because it makes important website information available to more types of crawlers.
2. Use Static Site Generation
Static site generation is another effective option.
It creates HTML pages during the website build process instead of generating every page when someone requests it.
This works especially well for:
-
Blog articles
-
Educational guides
-
Landing pages
-
Documentation
-
Product information pages
Static HTML is ready when a crawler requests the page.
It can also reduce server processing and improve loading performance.
3. Use Prerendering When Appropriate
Prerendering creates an HTML version of a JavaScript-powered page before a crawler requests it.
For example, a website may generate ready-to-read HTML for its important landing pages and blog posts.
This can be useful when changing the entire website architecture is difficult.
However, Google recommends server-side rendering, static rendering, or hydration rather than relying on dynamic rendering as a long-term workaround.
Make sure users and crawlers receive equivalent meaningful content. Avoid showing search crawlers a different article or misleading version of a page.
4. Keep Important Content Outside Click-Based Actions
Do not hide your main information behind buttons, tabs, or interactive elements that require user actions.
For example, your article introduction should be available when the page loads.
You can still use expandable sections for additional details, but important information should not depend on a crawler clicking a button.
5. Fix JavaScript Errors
A small JavaScript error can prevent an entire section from loading.
Open Chrome Developer Tools and select the Console tab.
Look for:
-
Red error messages
-
Failed API requests
-
Missing JavaScript files
-
Blocked resources
-
Hydration warnings
Fixing these issues can help your page render correctly for visitors and crawlers that execute JavaScript.
6. Check Your Robots.txt File
Even a perfectly rendered page may have visibility problems if crawlers cannot access the necessary resources.
Check your robots.txt file to make sure you are not accidentally blocking important pages, scripts, or stylesheets.
You should also review the access rules for individual AI crawlers.
For example, OpenAI provides separate controls for OAI-SearchBot and GPTBot. Allowing one does not automatically mean you must allow the other.
How JavaScript SEO Affects Generative Engine Optimization
Traditional SEO and GEO both depend on websites providing accessible, useful information.
However, GEO adds another important consideration: your content should be easy for AI-powered search systems to retrieve, understand, and potentially cite.
Imagine publishing an excellent article about digital marketing.
A visitor can read it because their browser executes the required JavaScript. But if an AI retrieval system receives only an empty HTML document, it may not have the article information available when preparing an answer.
This does not mean that JavaScript automatically hurts GEO. It means that content accessibility should be part of your technical GEO strategy.
Make Important Information Available in HTML
Your main article content should ideally include:
-
A clear H1 heading
-
Descriptive H2 and H3 headings
-
Complete paragraphs
-
Relevant internal links
-
Image descriptions and alt text
-
Structured data where appropriate
This makes your pages easier to process without depending entirely on browser-side execution.
Keep Your Content Easy to Understand
AI systems need clear information to understand what a page covers.
Use descriptive headings, explain technical terms, and answer important questions directly.
Avoid placing all meaningful information inside scripts, animations, or interactive components.
Monitor AI Crawler Activity
You can also review your server logs to understand which crawlers visit your website.
Look for known user agents such as:
-
OAI-SearchBot
-
GPTBot
-
Claude-SearchBot
-
ClaudeBot
-
PerplexityBot
-
Googlebot
Remember that crawler visits do not guarantee that your content will appear in AI answers. They simply provide useful information about access and crawling activity.
JavaScript Rendering Checklist for Website Owners
Before publishing a new article or landing page, review the following items.
Following this checklist can help reduce technical problems and make your website more accessible to different search systems.
Frequently Asked Questions
Does Googlebot Execute JavaScript?
Yes. Googlebot uses an evergreen version of Chromium to render JavaScript-powered pages. However, rendering may happen after the initial crawl, and some technical issues can prevent content from appearing correctly.
Do AI Bots Execute JavaScript?
It depends on the crawler. Some providers do not publish details about JavaScript rendering. Website owners should avoid assuming that every AI crawler works like Chrome or Googlebot.
How Can I Check If AI Crawlers Can Read My Website?
Start with the View Source test and curl. Check whether your main content appears in the original HTML response. You can also review server logs and use Google Search Console to inspect Google’s rendered version.
Is Server-Side Rendering Better for GEO?
Server-side rendering can improve content accessibility because important text is included in the initial HTML. This is useful for GEO because it reduces dependence on JavaScript execution by crawlers.
Can Client-Side Rendering Hurt SEO?
Client-side rendering does not automatically hurt SEO. Google can render JavaScript, but rendering delays, blocked resources, API failures, and other technical issues can create problems.
What Is the Difference Between SSR and Prerendering?
SSR generates HTML when a page is requested. Prerendering prepares HTML before the request, often during a build process. Both approaches can make important content available without requiring client-side JavaScript.
Should I Remove JavaScript From My Website for AI Visibility?
No. JavaScript provides useful features and improves many website experiences. Instead of removing it, make sure your important content is available in the initial HTML through SSR, static generation, or appropriate prerendering.